
Claude Fable 5.1 can work for hours while you sleep. Most people still use it in a chat window, pasting something in and copying the answer out.
That habit gets you frontier prices for an intern who grades their own homework.
Five weeks changed the math. Anthropic shipped Fable 5.1 on September 1, Opus 5.5 on September 22, Sonnet 5.5 on September 28 and Haiku 5.5 on October 7. Fable costs $10 per million input tokens and Haiku costs $0.10, so one company’s price list now carries a 100x spread (pricing).
For a founder in October 2026, the decision is who does which job and who checks it.
That setup has a name: an agentic OS. It’s the layer of scripts and ledgers around the model that lets it work alone and lets you trust what it hands back the next morning. Fable does the thinking, and the OS around it decides when a task is actually finished.
I expected the hard part to be the prompts. After building the kit for this piece, I found the prompts are the shortest files in it, and almost all the work lives in the plumbing.
Four things make the chat-window habit expensive with Fable:
-
The bill depends on who does the typing. In June, CopilotKit estimated it burned about $22,000 in one day after five Fable sessions spawned 2,122 sub-agents (CopilotKit; the company’s own estimate). I priced one ordinary working day (one morning plan, 6 tasks, 20 inbox emails) five ways, with the same assumptions for each. Fable doing everything with caching broken costs $90.75. With caching working, the same Fable-only day costs $21.70. Fable fanning out 10 copies of itself per task, each paying again to read the same files, costs $202.26. Fable planning while Sonnet 5.5 types and Opus 5.5 checks costs $8.02 for identical work. On a subscription, Claude Code bills any headless Fable request that would use usage credits “without asking” (model config). With Fable, the way you split work between models ends up deciding most of your bill.
-
It overstates its own progress. Anthropic says so itself. The system card for Fable 5.1 and Mythos 5.1, two models that share the same weights, says the model “often states easy-to-check guesses as facts” and “exaggerates the completeness of its work.” The Fable 5 prompting guide ships a paragraph to “ground progress claims during long runs,” which in Anthropic’s testing “nearly eliminated fabricated status reports even on tasks designed to elicit them.” The same guide carries the structural fix: “Separate, fresh-context verifier subagents tend to outperform self-critique.” Whichever model does the work, a different one checks it before the result reaches you.
-
The ground moves every few weeks. Fable 5 launched June 9, and three days later Anthropic switched it off for every customer after a US government directive (statement). The export controls were lifted on June 30 and access came back July 1. The free window on paid plans was first set to end June 22, then moved to July 7 (Redeploying Fable 5), then to July 12 (The New Stack), and closed on July 19 (Help Center). Fable 5.1 arrived September 1, and from September 24 some refusals that used to be free started showing up on the bill (what’s new in Fable 5.1). A setup that names its models in one config line treats each of those as a one-line edit, while a setup built around one model treats each one as an outage.
-
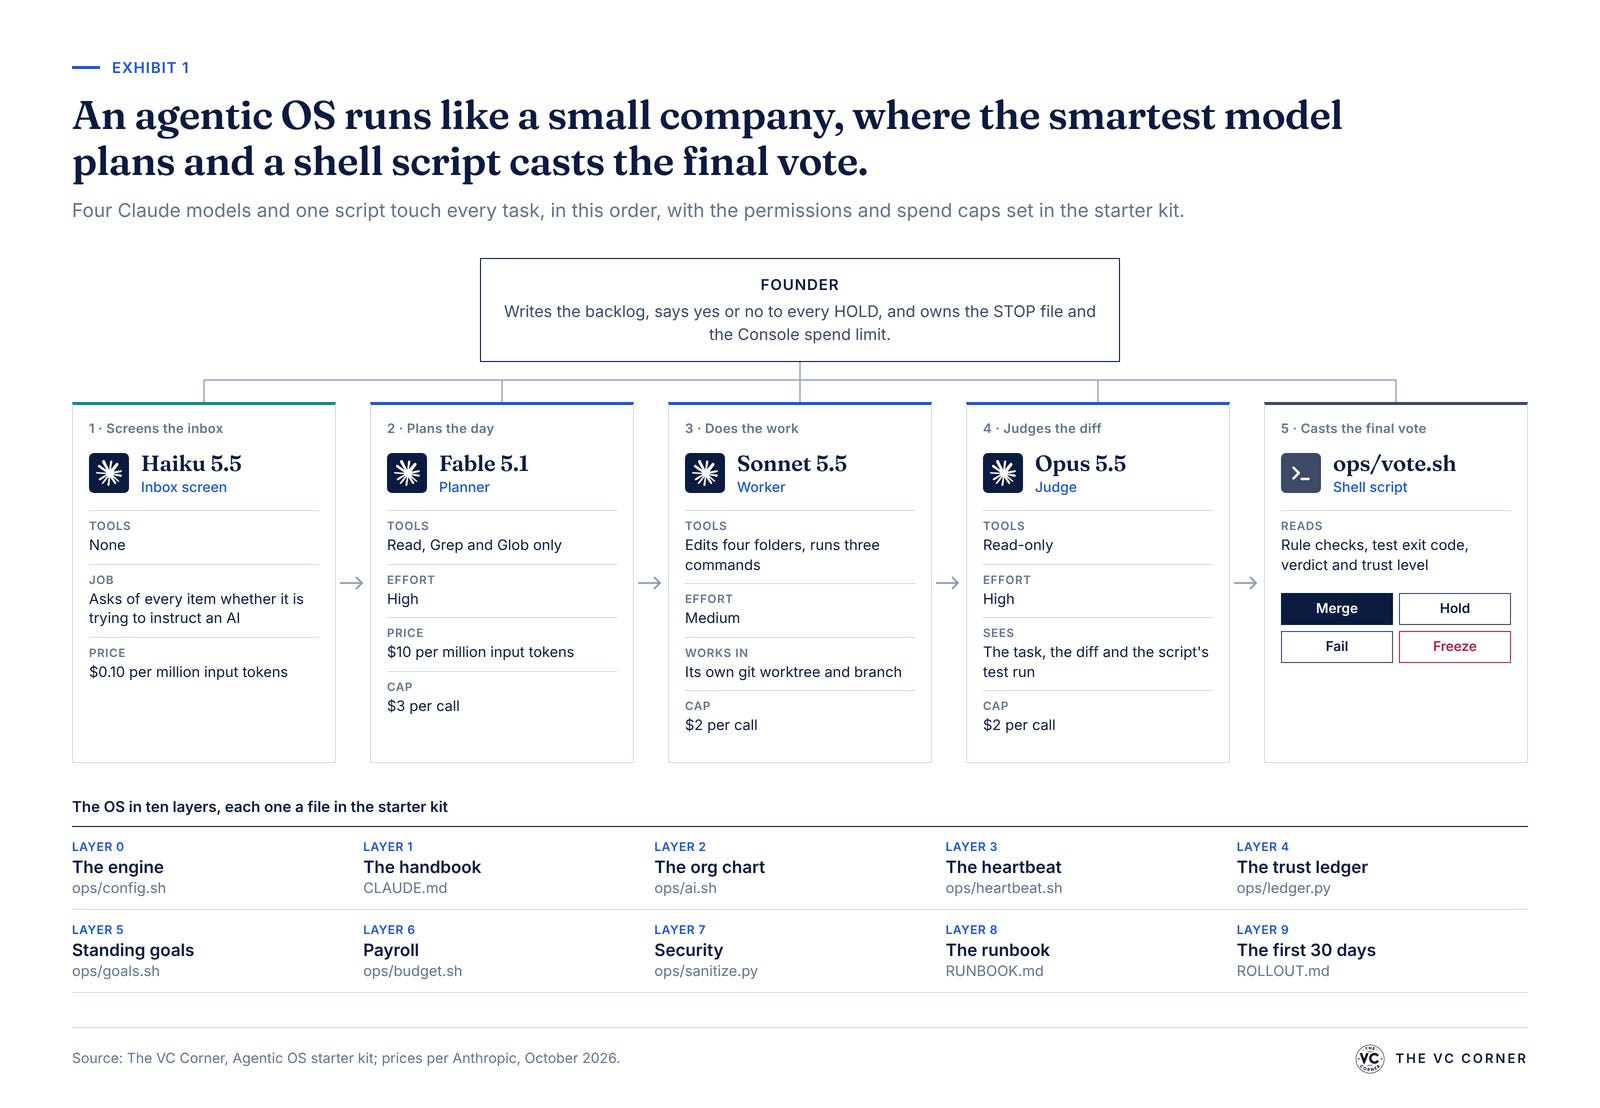
It reads text written by strangers. Once an agent reads your customer emails and GitHub issues, anyone who can email you can try to give it orders. Anthropic’s guardrails page states the goal: “Apply the principle of least privilege so that a successful injection can do minimal damage.” So in this OS, the model that reads strangers’ text has read-only tools, and the model that edits files sees just the task.
The rest of this guide builds the OS in 9 layers, each one a file you can open. By the end you’ll have:
-
A constitution of 8 hard rules, each naming the script that enforces it
-
An org chart of 4 models where the planner is read-only and the worker’s grade comes from someone else
-
A heartbeat: one cron script that runs the whole working day
-
A trust ledger that promotes a task type when the math says so and demotes it on its own
-
Standing goals that re-check every merged result every morning
-
A numbers check for investor updates that fails any figure missing from your data (my favorite file in the kit)
-
Three spending lines, the last one outside your machine
-
An inbox that screens strangers’ text before any agent reads it
-
A runbook for every alarm and a 30-day rollout
-
10 diligence questions for investors looking at “agentic” startups
Plus the starter kit: 37 files you copy into a repo, with sample data and a cost calculator included.
If you build, copy the folder and edit one config file, then run it once by hand. If you run a company, Layers 4 and 5 are the operating model: how work earns autonomy and how “done” stays true. If you invest, the last section turns all of it into questions for your next “agentic” pitch.
Four rules under everything
-
Every rule names its enforcer. Rules backed by a script hold up over time, while models tend to treat rules backed only by good intentions as optional.
-
Someone else grades the work. Four parties touch every task: Fable 5.1 plans it, Sonnet 5.5 does it, Opus 5.5 judges it, and a shell script casts the final vote. The script goes last because it applies the same check every time, whatever the models argue.
-
Autonomy is earned per task type, by the numbers. Docs can run alone long before code does, and investor updates always wait for you.
-
Done is a check that runs every morning. Every merged result leaves behind a test that re-runs daily, forever.
Layer 0 is the engine, and it’s the part that saves you money this week.
Layer 0: The engine in October 2026
Anthropic’s own advice is to “start with Claude Opus 5.5 for most workloads. Use Claude Fable 5.1 for demanding reasoning and long-horizon agentic work, or when your evals on Claude Opus 5.5 at higher effort still fall short” (models overview). Read that as a job description.
Fable 5.1 gets one job: the morning plan. It reads the backlog, yesterday’s report, the trust ledger and the inbox, then decides what happens today. That’s the one decision where a smarter model shapes the rest of the day, and it happens once a day, so everything else goes to cheaper models.
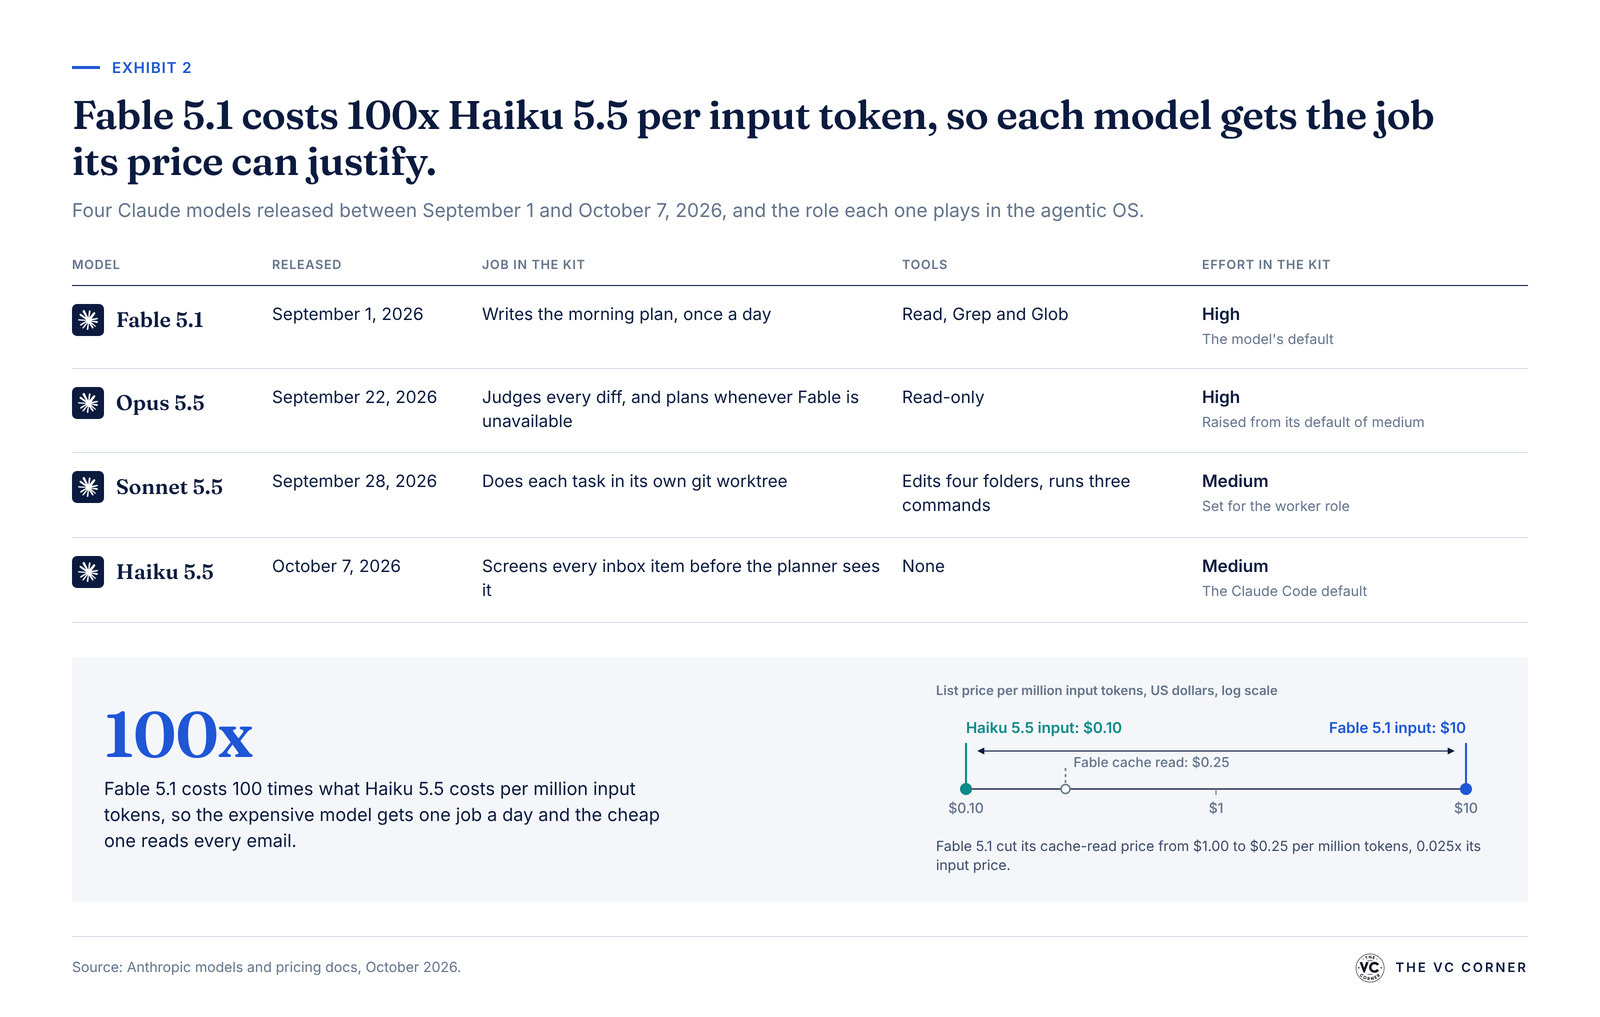
Every model takes an effort setting from low to max. The docs call it “a behavioral signal, not a strict token budget” that “affects all tokens in the response,” and lower effort “also means fewer and terser tool calls” (effort). Defaults differ by model: Fable 5.1 starts at high, Opus 5.5 at medium, and Claude Code runs Opus, Sonnet and Haiku 5.5 at medium.
The kit sets each role on purpose: high for the planner and the judge, medium for the worker. One line in the Fable 5.1 guide is worth testing on your own work: “At low, Claude Fable 5.1 is often competitive with Claude Opus and Claude Sonnet models on cost per task while scoring higher.” Fable on low as the worker is a setup I’d try in week three, once the ledger can tell you whether it held up.
Pay with an API key
How you pay changes what a cron job costs. On Max and premium Team seats, you “can use up to 50% of your weekly usage limits on Fable models at no extra cost.” Pro and standard seats pay for Fable with usage credits, and the API bills standard rates (Fable on your plan). In headless mode, Claude Code skips the consent prompt, so any Fable request that would bill to usage credits gets billed without asking.
So run the heartbeat on an ANTHROPIC_API_KEY with a workspace spend limit in the Claude Console, and keep your subscription for your own sessions. You get one bill to watch and a hard stop that lives outside your laptop.
What the setup costs
Here’s the day priced five ways, at Anthropic’s list prices. The call profiles (turns, context and cache hits) are my assumptions, and the kit’s calculator lets you swap in yours.
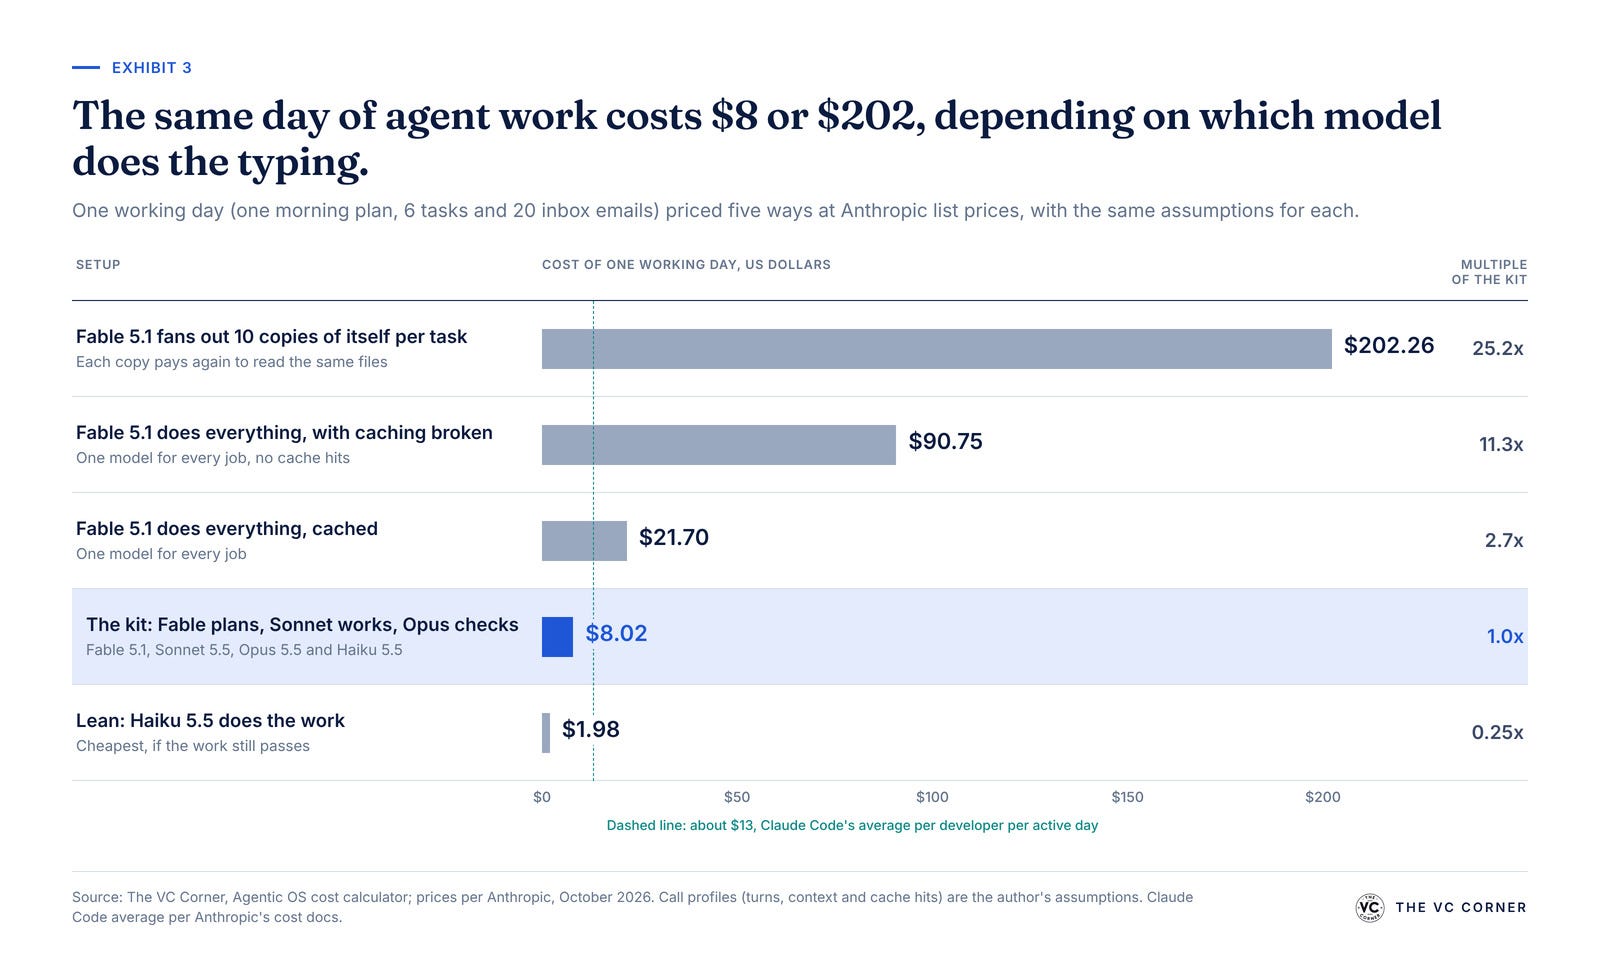
Caching is the biggest single lever. Fable 5.1 cut the cache-read price from $1.00 to $0.25 per million tokens, 0.025x the input price (VentureBeat, pricing), so a cached Fable session costs a fraction of an uncached one. The cheapest setup on the chart ($1.98, with Haiku 5.5 doing the work) saves money as long as the work passes, and the ledger in Layer 4 measures whether it does.
For scale, Anthropic’s Claude Code cost docs put the average at around $13 per developer per active day across enterprise deployments.
Paid subscribers get the rest of the build below: the 8-rule constitution, the heartbeat script, the trust ledger, the numbers check, the runbook, the 30-day rollout, the investor scorecard and the starter kit with the cost calculator.
Here’s the starter kit: 37 files, including sample data and the cost calculator. Download it now and keep it open while you read, because every layer below points to a file in it.
Read more